rcr-anti notes fewer tokens required for same results in Claude Code
1 Sep 21 12:45 PM · 5d ago · 2 articles · 1 post · 2 comments · 2 sources · development 1 of 6
A tracker of Claude Code performance disputes the degradation narrative, observing that newer versions require fewer tokens to achieve the same or better results, suggesting optimized prompt design and tool ergonomics rather than genuine capability loss.
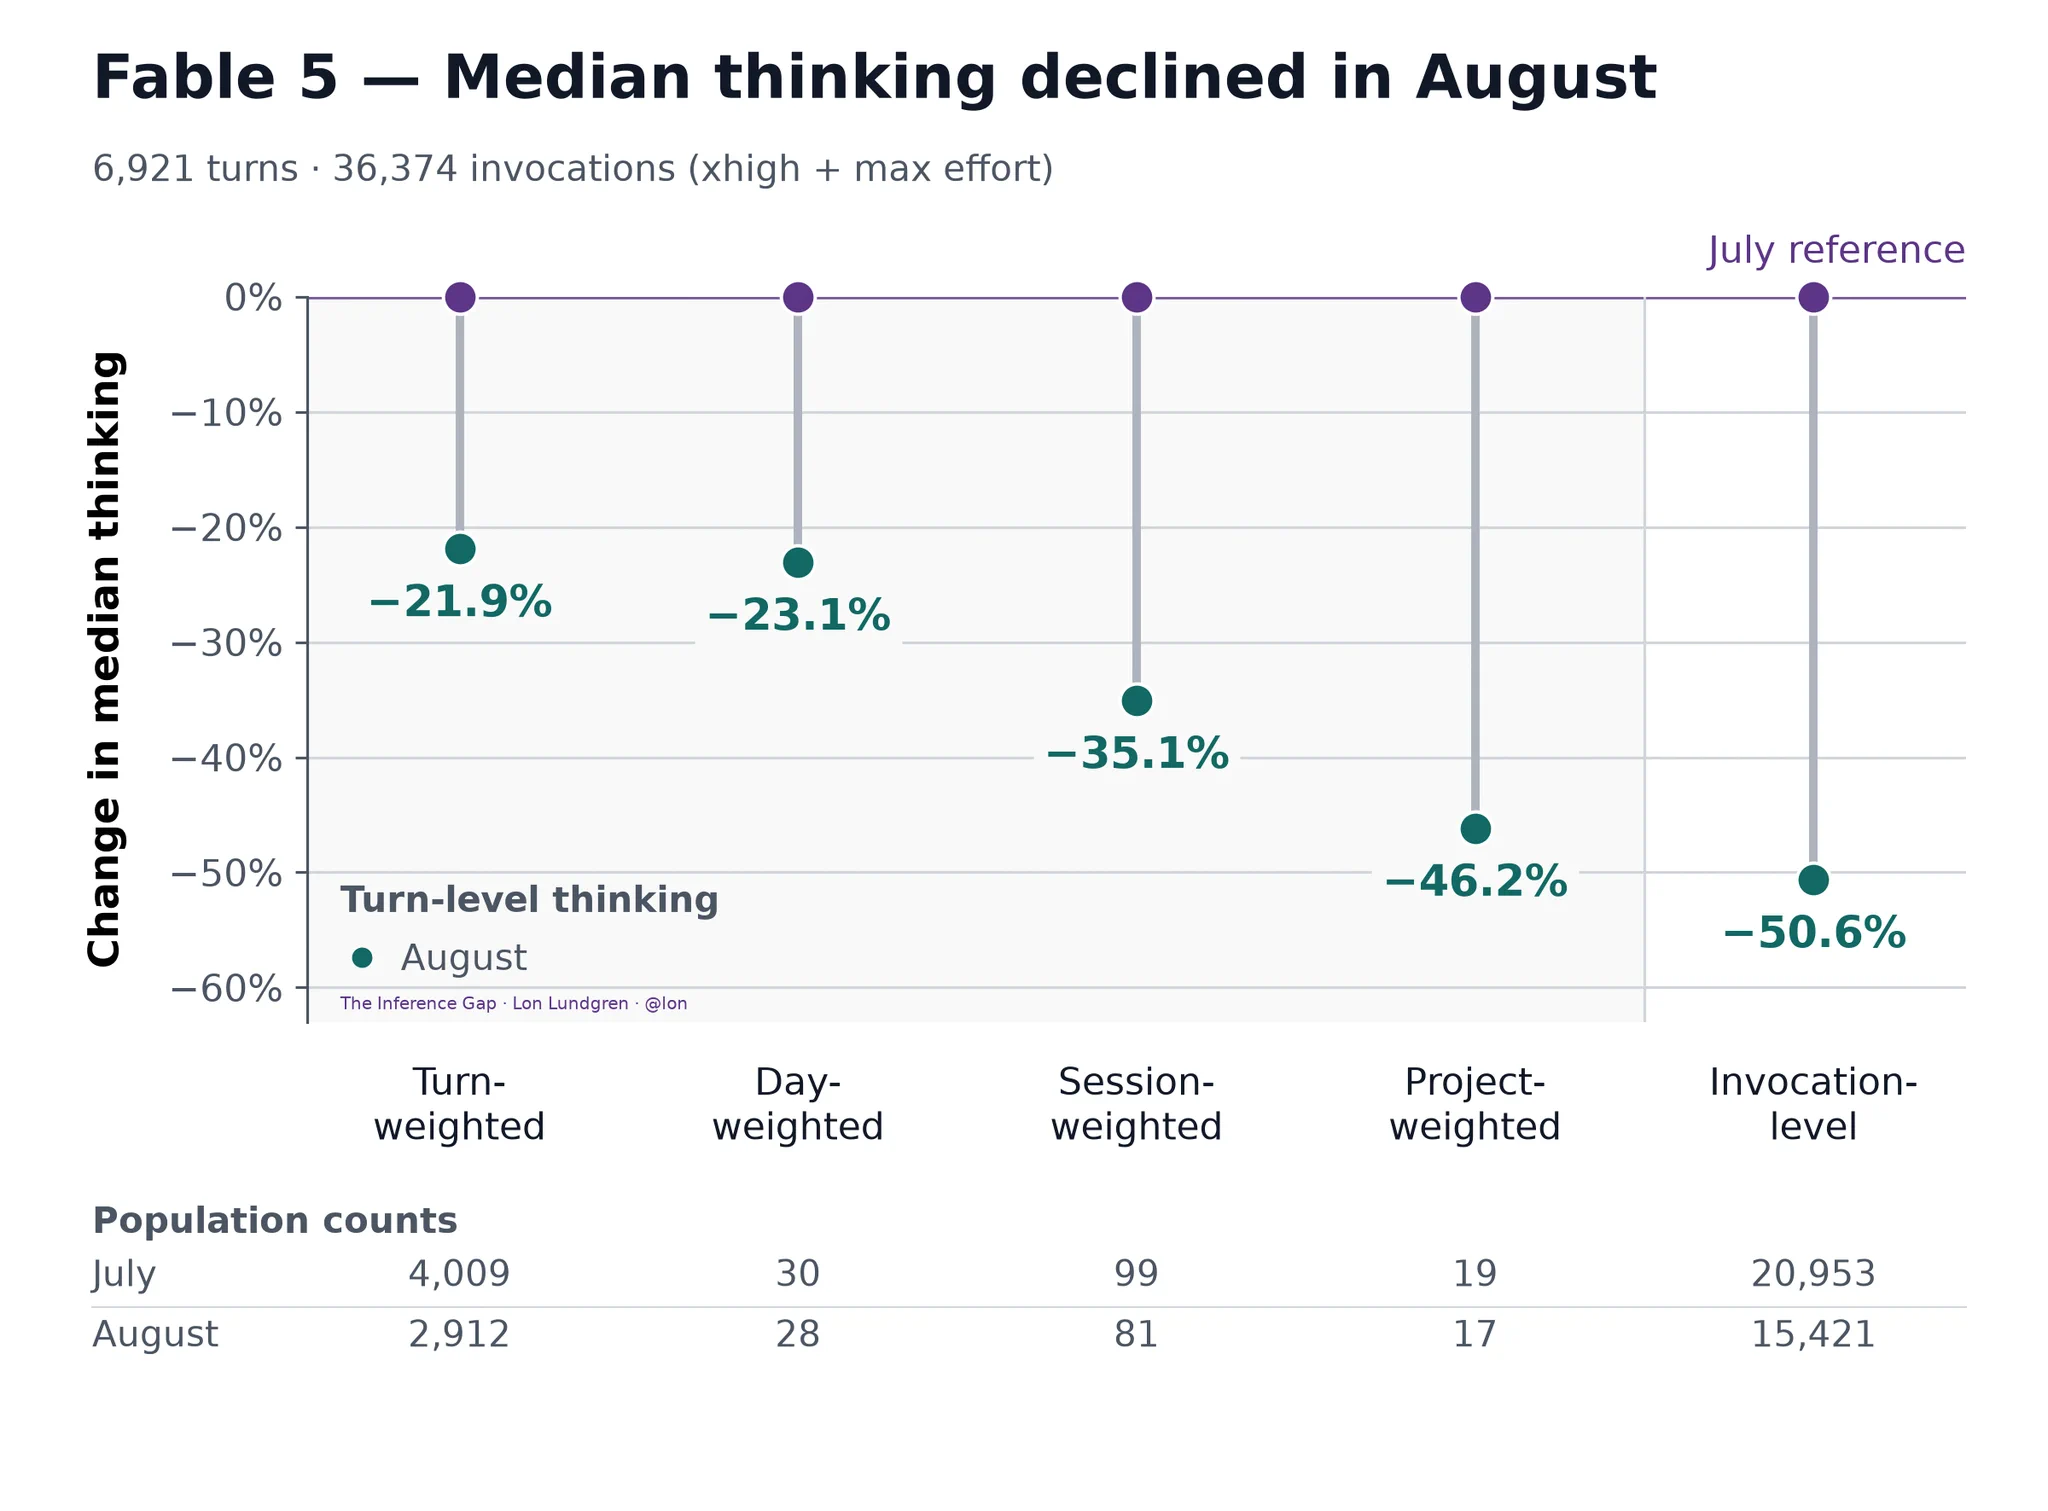
“Less thinking as measured by tokens isn't necessarily bad if you can get the same results by making it think about the 'right' things or structure.”
rcr-antiWaterluvian Fable 5 userjotato gpt-5.6-luna usermlmonkey Frontier model researchertheplumber Claude userrcr-anti Claude Code tracker
The whole story articlespostscomments the bright band is this development · numbered dots are the others · click one to jump
Reported in the same hours no headline names this development itself — these 1 claim were published in its stretch
-
first by HN Best, 5d ago · also HN Frontpage
What people said 2 voices · verbatim
-
Obviously. The standard pattern is that model X is basically AGI and wins all benchmarks, followed the next day by Y and Z, which both win all benchmarks, too.Then weeks later people find out that they have been duped and complain that the models have been quantized or employ worse inference.Buy decent coffee instead of your $200 subscription and…
-
I seem to recall Anthropic going on record saying that they don't do anything to model performance to stretch their compute capacity. I've anecdotally noticed massive peaks and troughs in performance week to week (albeit with Opus, not Fable).I wonder what their official explanation for this behavior is.
All 6 developments of Users report Fable 5 performance decline weeks after launch →
Hacker NewsNewswiresMastodon