Benchmark creators respond to latency criticism, describe methodology
5 Yesterday 12:47 PM · 12h ago · 3 comments · 1 source · development 5 of 6
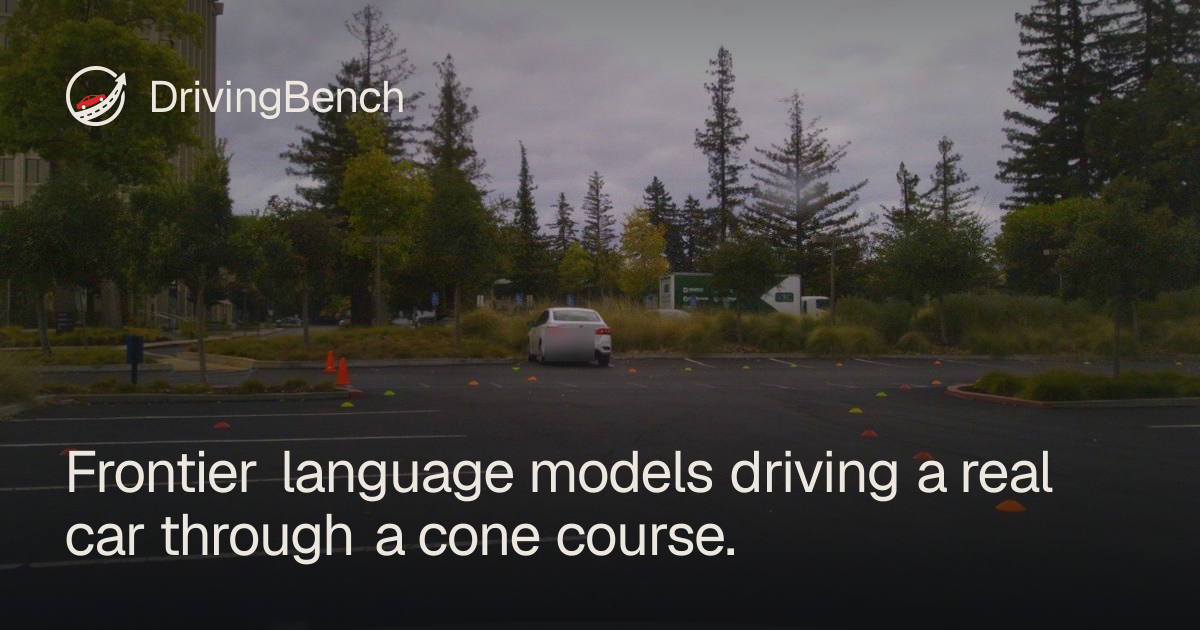
The researchers clarify that the benchmark is designed to measure frontier LLMs' out-of-the-box driving capability, not to demonstrate a practical autonomous system. They note the cars operate at extremely low speeds for safety and acknowledge latency as the core limitation.
“Great point! Yeah latency was one of the biggest issues here. To cope with that (and for safety reasons) the cars are driving at extremely low speeds.”
aditya-ramabadrOpenAI Creator of GPT-6 Astrajyoung8607 openpilot external contributor, benchmark commenterAditya Ramabadr et al. Benchmark creatorsvaline HN commenter
The whole story articlespostscomments the bright band is this development · numbered dots are the others · click one to jump
What people said 3 voices · verbatim
-
Great point! Yeah latency was one of the biggest issues here. To cope with that (and for safety reasons) the cars are driving at extremely low speeds. They also get timestamps with every tool call output etc so they can, in theory, "in context learn" about their own latency and choose motion durations and control how fast their iteration loop is…
-
> Could a cloud-delivered LLM figure out how to drive this route, based on those input data and given access to those output actuators? Looks like yes. Sure.Well, if the massive cloud models that are generalized and have a world model that's good enough, you can just distill them into smaller models. As a point of reference, the current gen of…
-
Looking forward to the juggling bananas benchmark. If Claude can only manage 5 and Astra does 6, clearly they have a better model.
All 6 developments of GPT-6 Astra successfully drives a real car in benchmark test →
Hacker NewsNewswiresMastodon