jotato describes model degradation over 2-3 weeks
3 Sep 21 12:58 PM · 5d ago · 2 comments · 1 source · development 3 of 6
A user reports that gpt-5.6-luna, which performed as well as the previous model version in its first week, has become noticeably worse in the last 2–3 weeks, requiring explicit prompting for tasks it previously handled implicitly.
“over the last 2 or 3 weeks I've seen how dumb it is now. I have to be very explicit with it.”
jotatoWaterluvian Fable 5 userjotato gpt-5.6-luna usermlmonkey Frontier model researchertheplumber Claude userrcr-anti Claude Code tracker
The whole story articlespostscomments the bright band is this development · numbered dots are the others · click one to jump
What people said 2 voices · verbatim
-
Just yesterday I was thinking about gpt-5.6-luna. I made it my default model in Hermes during its fist week of launch. It was just as good as 5.5 which was my previous default. But over the last 2 or 3 weeks I've seen how dumb it is now. I have to be very explicit with it.For example, I used to be able to prompt "Check the system logs on <server>…
-
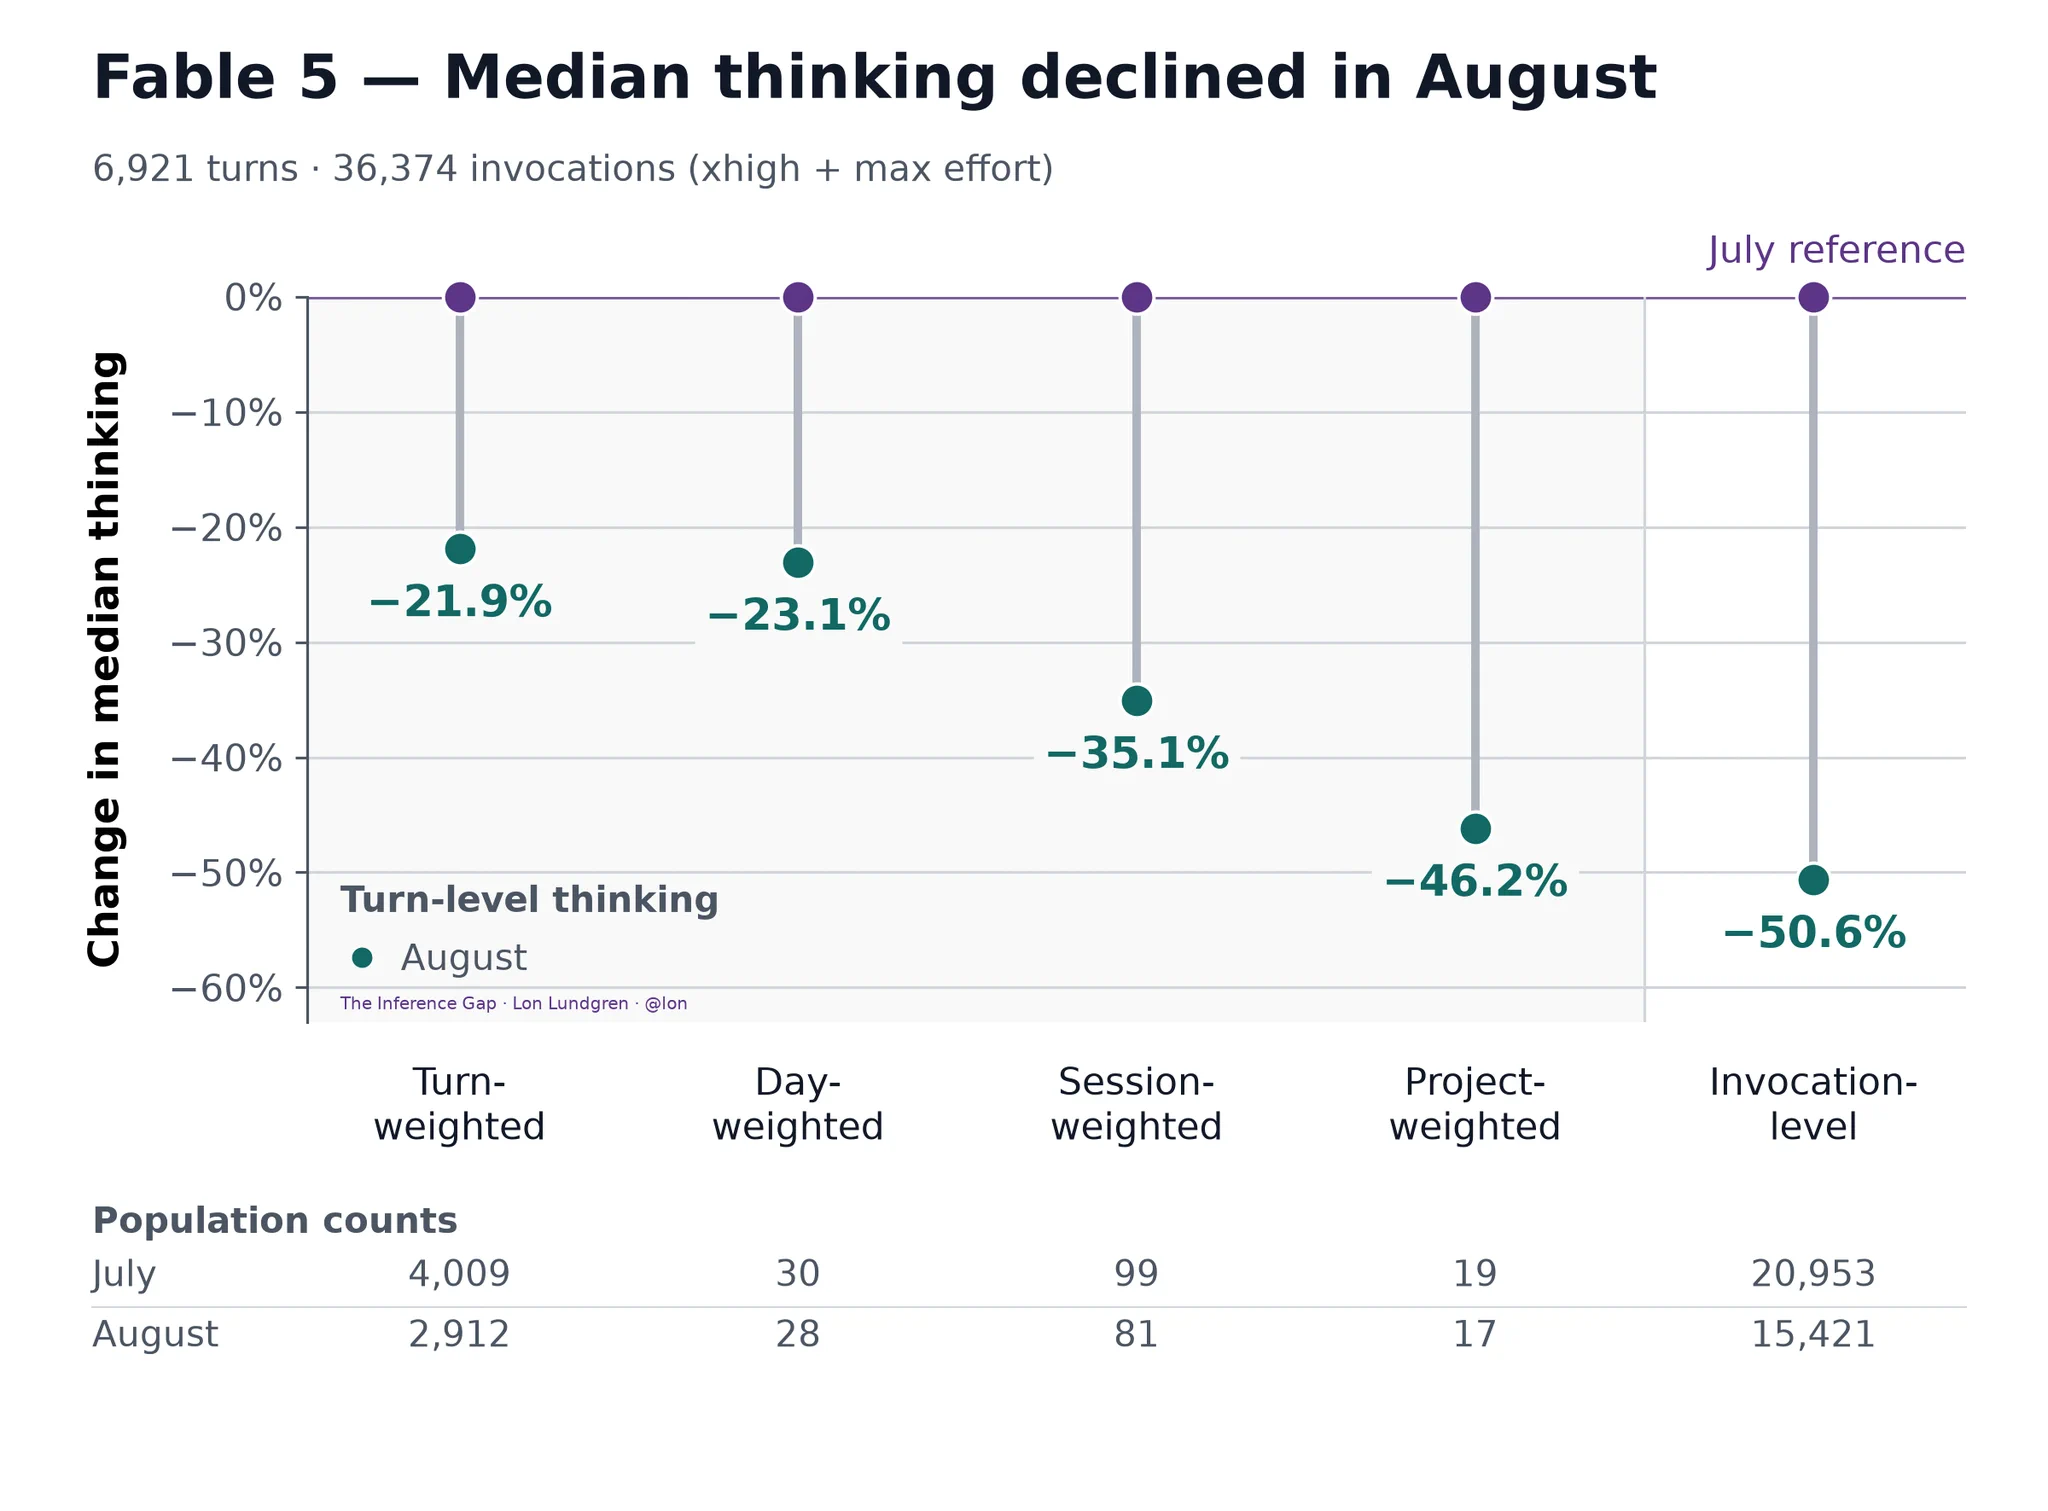
It is clear by now to me that Anthropic is constantly trying to find a kind of “auto” degradation perhaps to save money on work it thinks does not require high reasoning. I always use max reasoning and I can clearly see differences between the models when they release and after 3-4 weeks. I think they give a kind of intelligence boost also for new…
All 6 developments of Users report Fable 5 performance decline weeks after launch →
Hacker NewsNewswiresMastodon