AIQuiet 26d · day 27
Anthropic releases Claude Fable 5.1, tested with pelican SVG benchmark
New model claims coding and research gains; Simon Willison's informal pelican-drawing test shows sharp differences across reasoning levels.
What to know
- Anthropic's Claude Fable 5.1 claims a 52.6% score on the new Terminal-Bench-Science 0.1 benchmark, up sharply from prior models (24.7% Fable 5, 29.0% Opus 5, 22.4% GPT-5.6 Sol).
- The model has five reasoning effort levels (low, medium, high, xhigh, max) with no way to disable reasoning entirely.
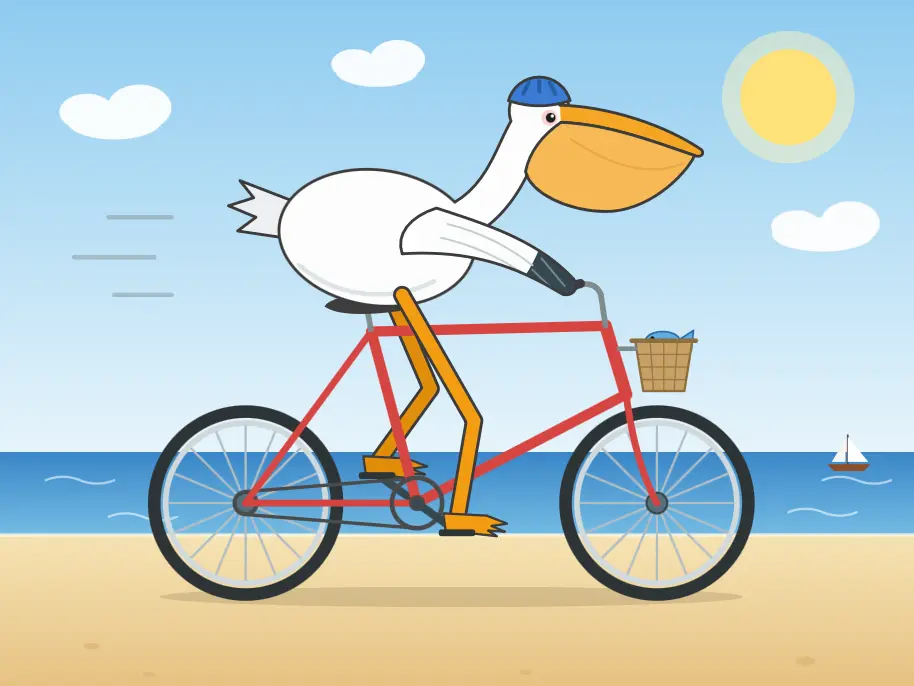
- Simon Willison's pelican-SVG test showed low and medium effort produced nearly identical, reasoning-free outputs, while max effort used 65,927 output tokens, took nearly 14 minutes, and cost $3.30.
- Willison notes the pelican benchmark's usefulness has declined for comparing models overall but remains informative for comparing reasoning-effort settings within one model family.
“I'll accept the slight thickness as charming rather than overengineering it.”
Claude Fable 5.1 (via reasoning trace), AI model reasoning output · Simon Willison's blog · Aug 31
Anthropic AI company, developer of ClaudeSimon Willison Independent developer and blogger
The record 2 articles and posts · last 27 days