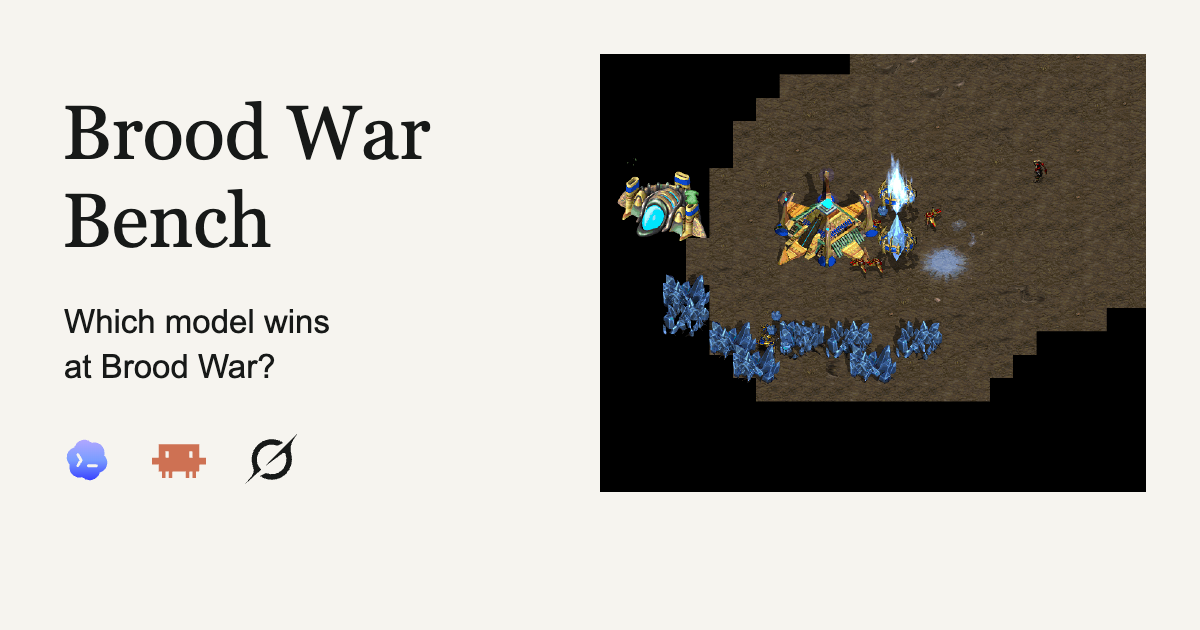
Brood War Bench pits AI coding agents against each other in StarCraft
A hobbyist built a benchmark that lets Codex, Grok, Claude Fable and other models play full games of Brood War, exposing sharply different failure modes.
What to know
- Brood War Bench lets LLM agents (Codex, Grok 4.6, Claude Fable, others) play full StarCraft: Brood War games against each other with no human control.
- Models show distinct failure patterns: Codex's harassment tactics work but its production and coordination are weak; Grok reasons extensively but acts rarely; Claude Fable is the most ambitious economically.
- Even the best-performing agents remain far below basic human skill — the creator notes a beginner doing a simple photon rush would beat every model tested.
- Commenters situate the project against older AI-StarCraft research (a 2010 UCSC Brood War AI tournament, DeepMind's SC2 work) and a separate LLM Go benchmark (GoBench), and ask for clarification on how agents actually interface with the game.
The dispute Whether Brood War Bench meaningfully differentiates model capability, versus commenters pointing to alternatives like GoBench as showing clearer capability gaps. · positions read across 40 posts and comments
The post mainly triggers personal nostalgia about StarCraft/Brood War as a formative community and hobby, largely separate from the AI angle.
-
“I miss those days so much.”
pelagicAustral · Hacker News ↗
The benchmark's methodology and real capability differentiation are unclear, and other approaches (older AI tournaments, GoBench) are cited for comparison.
-
“Did it play by looking at screenshots and sending clicks, or was there other mediation/symbolization?”
gadtfly · Hacker News ↗
StarCraft's three factions offer a useful playful metaphor for how to think about deploying different kinds of AI agents.
-
“Protoss: powerful and expensive frontier coding agents you directly micromanage for the toughest tasks”
mcteamster · Hacker News ↗
“This worked shockingly well as the opposing agents often spent dozens of seconds thinking about what to do about a probe instead of doing anything else.”
benswerd, Benchmark creator · bw.swerdlow.dev/report ↗ · Sep 18
benswerd Creator of Brood War BenchOpenAI Codex AI agent tested in the benchmarkGrok 4.6 (xAI) AI agent tested in the benchmarkClaude Fable (Anthropic) AI agent tested in the benchmark
How it unfolded 3 developments, newest first · click a bar or a number to jump articlespostscomments
-
3
Report is mirrored and picked up beyond Hacker News
The same report text was republished/linked via a Mastodon bot account tracking HN frontpage stories, spreading the findings to a wider audience.
“Protoss: powerful and expensive frontier coding agents you directly micromanage for the toughest tasks…”
— mcteamster, HN commenter · source -
 G
Have trouble picking the right # benchmark about AI agents/models? also played # rts # games ~30 years ago? then you might find Brood War Bench fascinating 😜 https:// bw.
2 more of the top 3 · 31 posts in this stretch
-
This is a very interesting benchmark, and I think it has a lot of potential to make the speed of a model quantifiable.I'm often asking myself is it better to use higher or lower effort levels, or to maybe drop down to a "dumber" but faster model. And so using a real-time based competition as a benchmark could shed some light on this, I think.In…
-
 H
Brood War Bench Link: https:// bw.swerdlow.dev/report Discussion: https:// news.ycombinator.com/item?id=4 9766966
-
-
2
HN commenters question methodology and compare it to prior AI-StarCraft work
Commenters asked whether agents played in real time via screenshots/clicks or through some other symbolic interface, and drew comparisons to a 2010 UC Santa Cruz Brood War AI tournament and to DeepMind's SC2 agents, as well as a separate LLM benchmark on 9x9 Go (GoBench).
“Did it play by looking at screenshots and sending clicks, or was there other mediation/symbolization?”
— gadtfly -
2 outlets Brood War Bench
first by HN Best, 8d ago · also HN Frontpage
-
Back in 2010, during the early days of bwapi, there was a Brood War AI tournament held by the Expressive Intelligence Studio at UC Santa Cruz. It's interesting to see how different the approaches were back then, vs this or Deepmind's SC2 work.https://web.archive.org/web/20091124210529/http://eis.ucsc.e...There's a great contemporary Ars Technica…
2 more of the top 3 · 9 posts in this stretch
-
Unrelated to the benchmark...I love StarCraft. I started playing it right from the beginning, most of my friends right now are from that era. I literally met people that have spread to almost every continent when I was in my early teens. We played at internet cafes and did not have access to the internet, that was priced differently...I miss those…
-
A friend of mine created GoBench[1][2] that evaluates LLMs on 9×9 Go using KataGo opponents as Elo anchors, you see real capability differences there, like Astra Max substantially leading all other models. I think strategy is a generally interesting area to evaluate LLMs on[1]
-
-
1
Report details model-specific strategies and failures
The write-up describes Codex's effective but shallow Probe-harassment tactics, its subagents' poor coordination, Grok 4.6's long reasoning traces with almost no issued commands, and Claude Fable's comparatively ambitious tech-climbing and economy-building, while stressing that a beginner human doing a photon rush would beat every model tested.
“Codex's strongest recurring idea was disruption.”
— benswerd -
background
benswerd publishes Brood War Bench, an AI-agent StarCraft benchmark — The project grew out of an agent-only version of Brood War the creator built to play with friends; after friends won by simply telling their agent to attack, benswerd built a formal benchmark testing how far AI agents can get on their own.
What people are saying 17 voices from 2 sites · best of 40 · verbatim
- Did the agents play in true real time via screen input, or through some discretized/turn-based interface?
- Sep 20
-
OSN did it on their youtube for their old OSL series, I think it can be done better but I think original still is much better to look at, at a corresponding resolution.The key expression for playlists or yt browsing is this `AI 업스케일`f.e.
-
I had a similar idea for Super Smash Bros Melee! There is a lot of very low-quality footage out there; surely you could train some sort of model to convert it to Slippi replays. A year or two ago this would have been a grad student project; a year or two from now, it will be a one-shot prompt.
-
Astra had an explicit medium/xhigh levels, Fable - just Fable. What reasoning level was used? Why not multiple were tested?I’ve scrolled the article, but haven’t noticed any remarks about Fable’s levels.
-
It was the late 90s, my very first day at a new school, I was asked to introduce myself at the front of the class, I mentioned I like computers, one guy at the back of the class blurts out “En Taro Adun” and without skipping a beat I replied “J’tokoh zohl”, and we instantly became best friends.
-
I also entered the competition as an undergrad—I contacted Ben Weber 10 years later (2020) and interviewed him on my podcast:
-
“Older models tended to play the RTS as a turn-based game, leading them to get destroyed while they were thinking. ”That’s me. I’ve always struggled with real-time games because I need to pause and think. While I excel at chess and board games, I’m just no good at real-time ones. At last I can only manage by sticking to a fixed set of tactics for…
-
I like this as a concept - taking a very real world task and checking whether it works.Surprised the outcomes are so poor though. I recall years ago AI was capable of beating pro level DOTA teams.I guess in one case it was specifically trained on the interface & game while here it was not?
-
 N
Brood War Bench: https:// bw.swerdlow.dev/report Discussion: http:// news.ycombinator.com/item?id=4 9766966
-
All the hobbyists were using proxybot because it allowed you to use more fun languages than C/C++ but proxybot lacked the features to effectively play Zerg. I really wanted to play Zerg so I built a really sweet API+DSL in Ruby around proxybot and then used that to give the other newbies a hard time with a zergling rush.Unfortunately the proxybot…
-
Your minds will be blown when you realize just how much StarCraft is ingrained into South Korean culture. They literally had (or have) dedicated TV channels just for StarCraft.Brood War was the first video game to be broadcast on TV in Korea. I'm pretty sure it's still going.
-
This thing kept me sane through university. I had a shitty computer which could barely run this and no Internet so I just played against the computer, which was both frustrating and educational.I will always love this and now I'm going to play it again. Remastered and on a fancy modern machine.
- Sep 19
-
I don't know where else to write this, but I want to throw the idea out there. I have long wanted to take old broodwar televised matches, many of which are terrible quality 240p, and use machine learning to convert them to into perfect Broodwar Remastered frames. This seems tractable to me because you should be able to map the terrain sets to…
-
I love this. Funnily enough StarCraft has influenced how I approach AI at a meta levelProtoss: powerful and expensive frontier coding agents you directly micromanage for the toughest tasksTerran: versatile team comps of dedicated agent roles you can delegate well-defined tasks toZerg: massive swarms of specialist custom agents inside your apps…
-
Same and Brood War is starting to have a bit of a resurgence. Not anything huge. When Battle.net servers are actually working, tend to play on the ladder a few times a week. Get crushed, but still one of the greatest competitive games ever made.
-
Oh boy, I've spent more hours playing it than I dare to admit. I won over 10000 battle.net games ... on just one of my several accounts :) When the SC2 beta came out, I played about 50-100 games and never bought the full game, because I knew it would be like heroin to me, and I was already an adult that had to take care of himself.
-
If you want to see human written bots in action or compete in the bot ladder yourself, try
-
I agree.My first time playing StarCraft was at summer camp around a decade after it came out.All the smartest people played it so I wanted to too. Great decision, I have been continually impressed with the people who StarCraft introduced me to.