AIQuiet 4d · day 4
MiMo-V2.6 tops open-weight LLM benchmarks with simple architecture
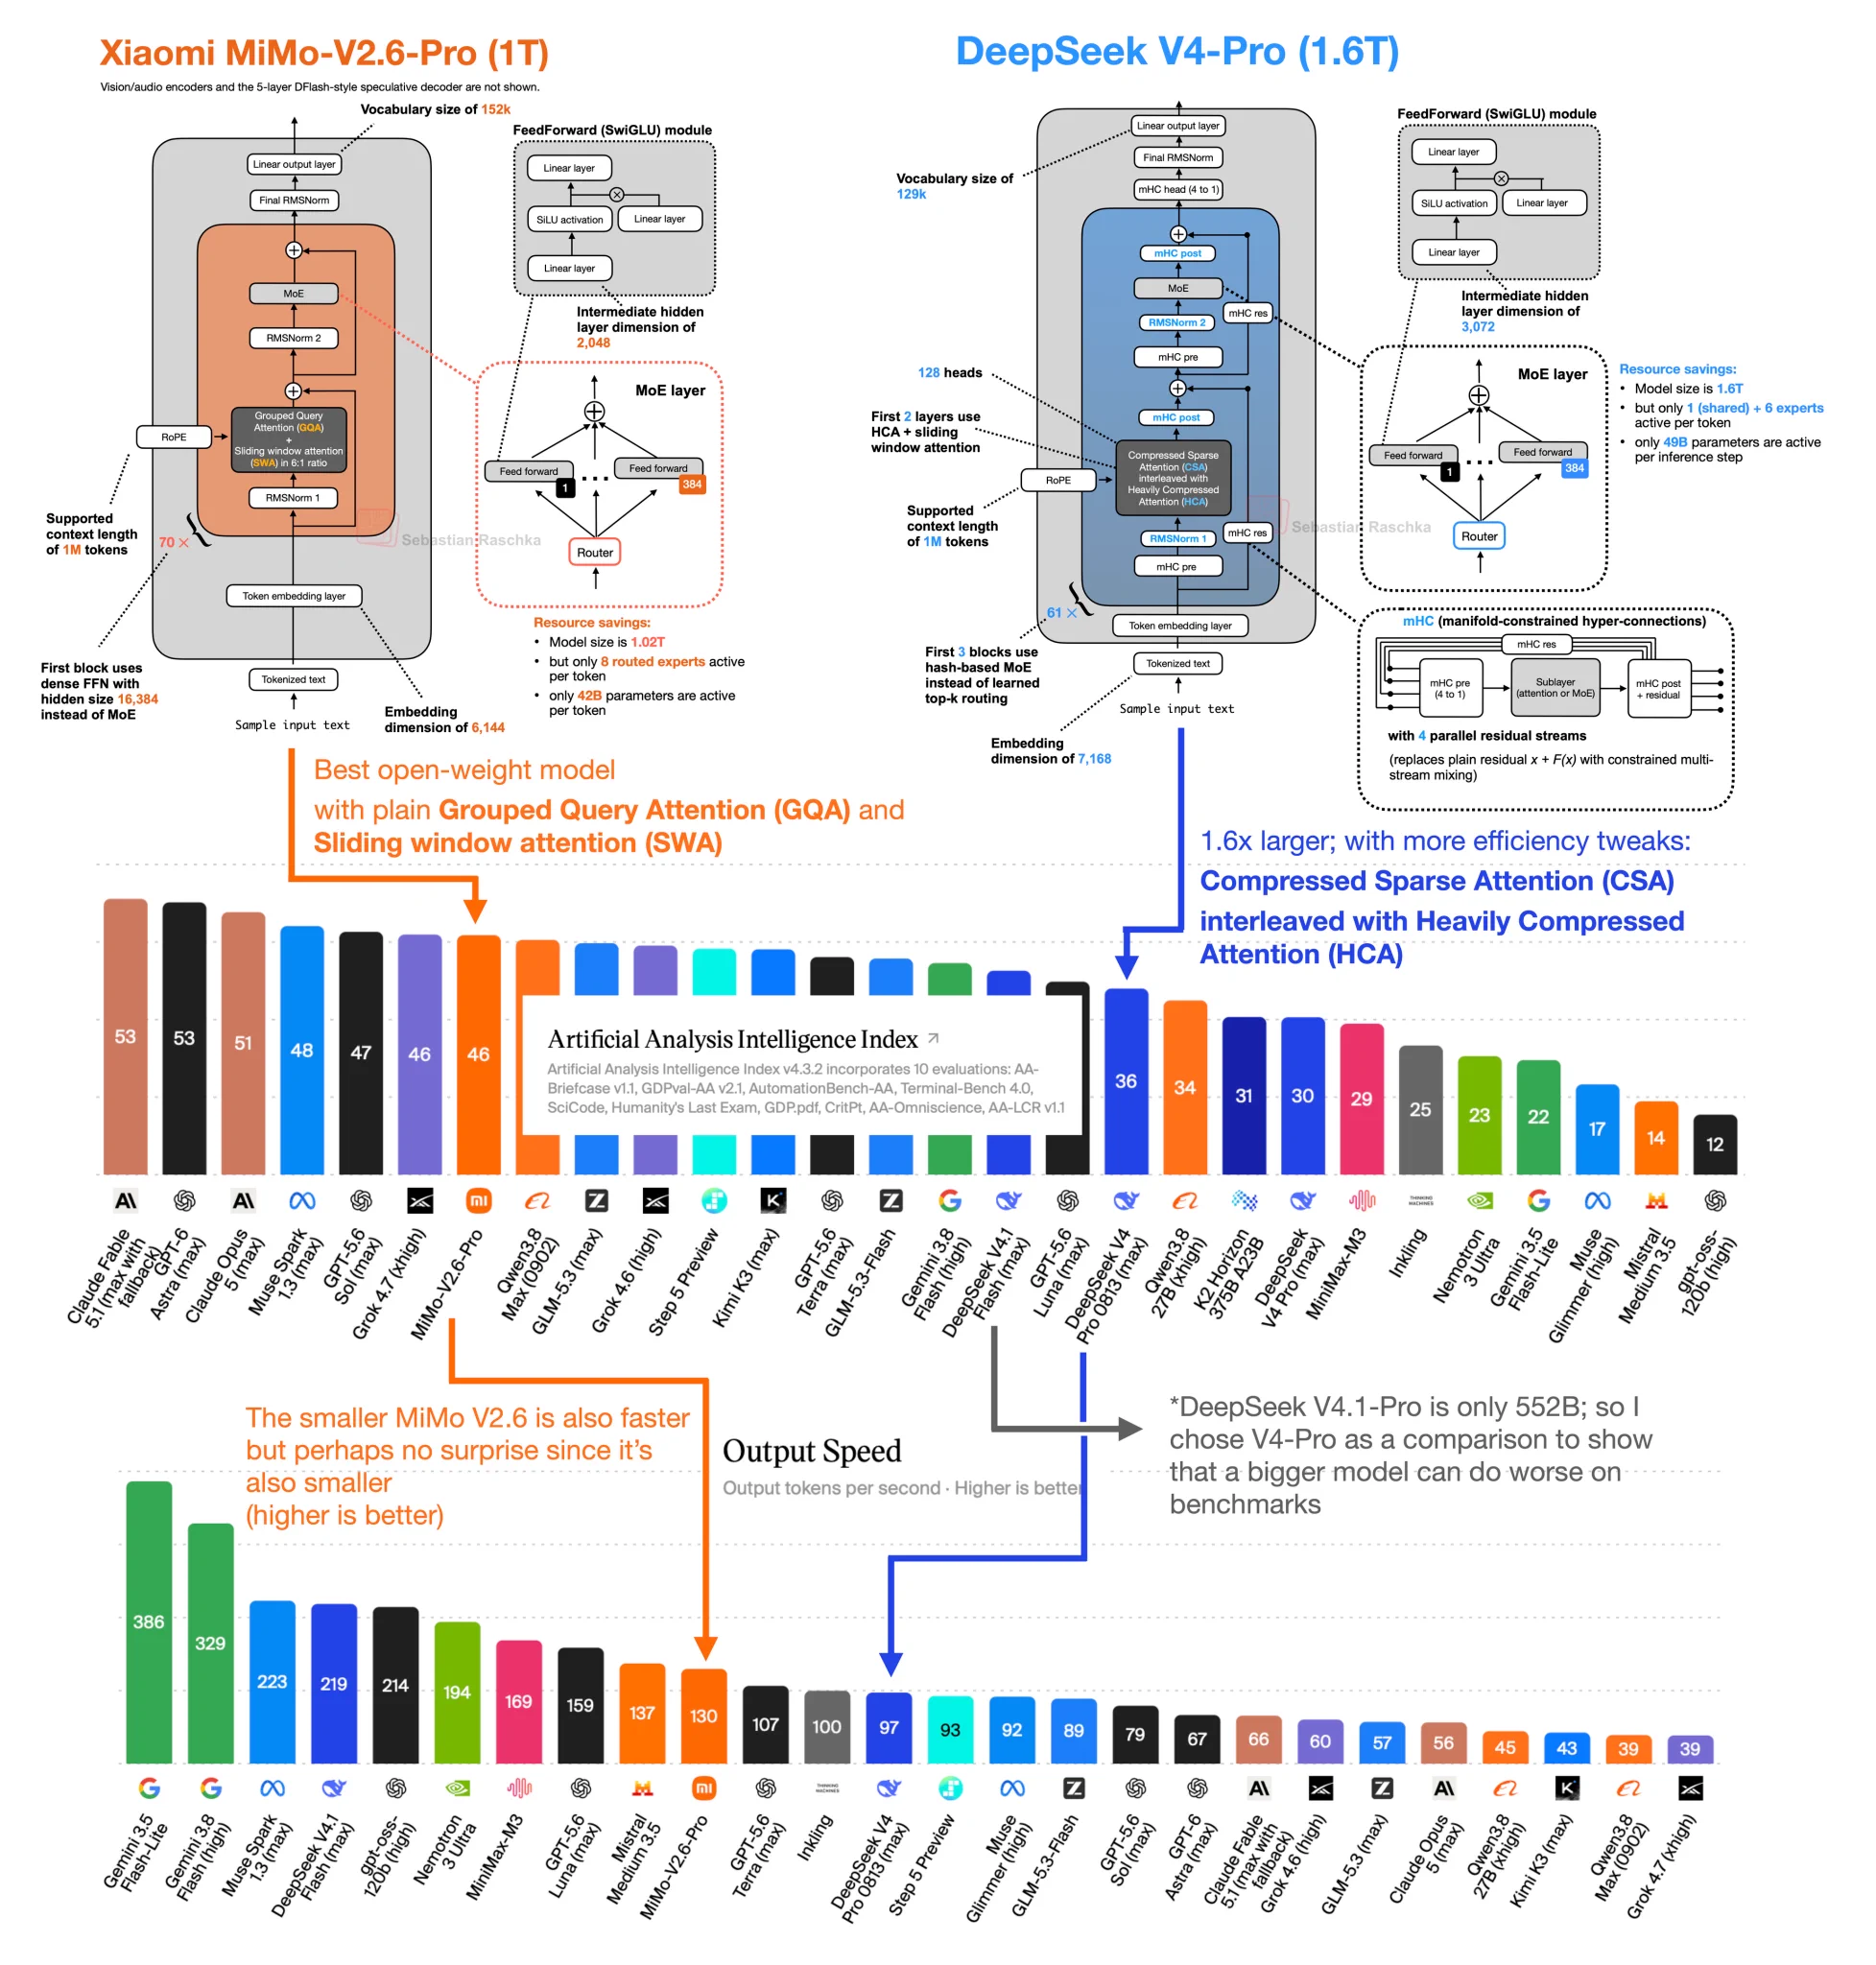
Sebastian Raschka highlights the model's ranking using basic Grouped Query Attention and Sliding Window mechanisms.
What to know
- MiMo-V2.6 ranks first in open-weight language model benchmarks by weighted average, according to Raschka.
- The model achieves top performance using straightforward techniques: Grouped Query Attention with minimal 128-token Sliding Window Attention.
- The announcement suggests architectural simplicity need not sacrifice benchmark performance in open-source LLMs.
Sebastian Raschka Machine learning researcher
How it unfolded 1 development · click the chart to see its coverage posts
Sep 22Sep 23Sep 24yesterdaynow · 8:29 AM ET
-
1
“MiMo-V2.6 is "simply" the best (for now). Despite its simple architecture design it's currently No.1 in the open-weight benchmarks (weighted average).”
— Sebastian Raschka -
MiMo-V2.6 is "simply" the best (for now). Despite its simple architecture design it's currently No.1 in the open-weight benchmarks (weighted average). With "simple," I mean a classic Grouped Query Attention (GQA) with Sliding Window Attention (SWA) at a tiny 128-token window
-