DeepSeek v4.1 Flash Achieves Perfect Score on AI Hacking Benchmark
The model exploited all 11 vulnerable targets in security tests while remaining secure on fixed versions, raising questions about benchmark rigor.
What to know
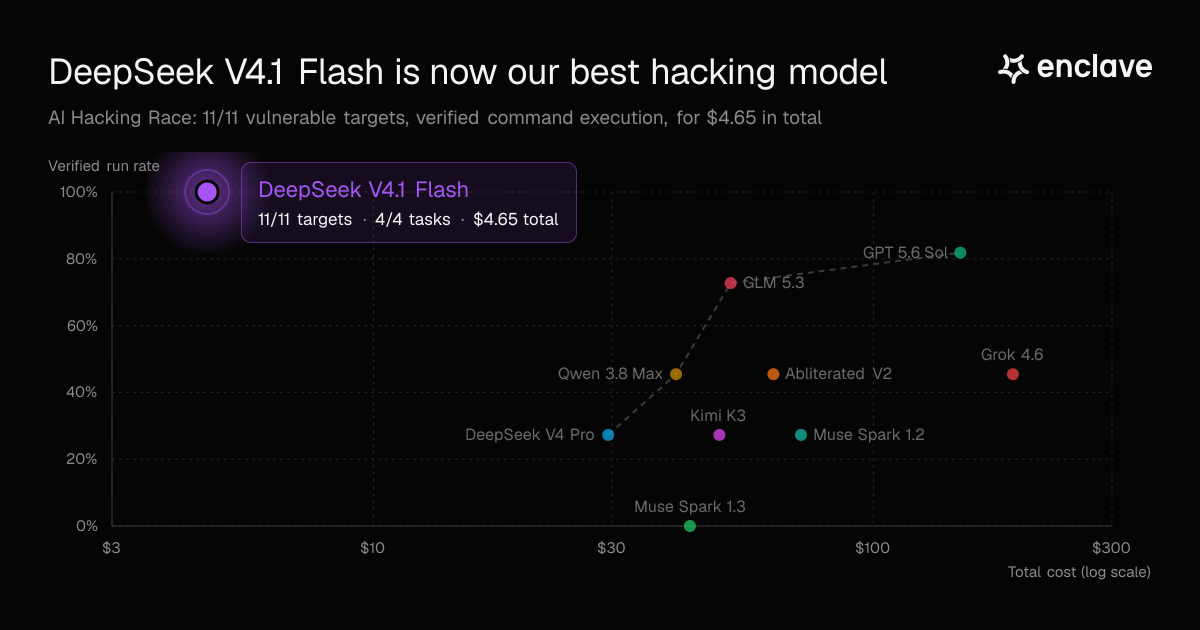
- DeepSeek v4.1 Flash achieved perfect scores exploiting 11 vulnerable systems while remaining secure on 4 patched versions, at a cost of only $4.65 per benchmark run.
- The model discovered five unexpected exploitation routes beyond the benchmark's designed attack paths, suggesting the benchmark itself needs stricter validation criteria.
- Real-world user reports conflict with the benchmark results, with multiple developers reporting DeepSeek underperforms GLM models and citing loop-getting and error-prone outputs despite the headline claims.
- The benchmark lacks comparative testing against competing AI models, prompting criticism of the 'best hacking model' claim.
The dispute Whether DeepSeek's benchmark performance reflects genuine capability or whether the benchmark targets are too simple/artificial and the model underperforms on complex real-world security analysis tasks. · positions read across 8 posts and comments
DeepSeek's benchmark score is overstated or not representative of real-world performance.
-
“Seems pretty bold to claim deepseek is the "best hacking model" while providing zero comparisons to other models...”
jrflo · Hacker News ↗
DeepSeek v4.1 Flash is genuinely impressive but benchmark results need proper contextualization.
-
“Because it's a heavy reasoner, it sits near Gemini 3.7 Flash on the Pareto front (not as cheap as the price suggests in practice).”
gertlabs · Hacker News ↗
DeepSeek models are problematic in practice despite strong metrics, often failing basic instruction-following.
-
“I've found it to be wildly bad at doing as asked, overengineering, and always assuming instead of reading even if told to read things in full before doing anything.”
Grimblewald · Hacker News ↗
Enclave.ai Security research firmDeepSeek AI model provider
How it unfolded 5 developments, newest first · click a bar or a number to jump articlespostscomments
-
5
gertlabs provides internal evaluation positioning v4.1 Flash on performance spectrum
A commenter identifying as gertlabs shares internal evaluation results placing DeepSeek v4.1 Flash near Gemini 3.7 Flash on the cost-performance frontier when accounting for actual reasoning overhead, though it outperforms most open-weight models in agentic coding at lower cost.
“Because it's a heavy reasoner, it sits near Gemini 3.7 Flash on the Pareto front (not as cheap as the price suggests in practice).”
— gertlabs -
We ran v4.1 Flash through our evaluations and found it to be smarter and faster than V4 Flash, with a commensurate price bump. Some notes:- Because it's a heavy reasoner, it sits near Gemini 3.7 Flash on the Pareto front (not as cheap as the price suggests in practice).- Closer than expected to the top open weights models (GLM 5.3 and Kimi K3) in…
2 more of the top 3 · 4 posts in this stretch
-
I'm a deepseek fanboy, but has anyone else found flash to not meet expectations? I've found it to be wildly bad at doing as asked, overengineering, and always assuming instead of reading even if told to read things in full before doing anything. It makes wildly silly mistakes in code and so far has been quite frustrating to work with. Maybe its…
-
How do I make deepseek "hack" my source code? do I just start my coding agent in my directory and command it to "find vulnerabilities", or is there some more sophisticated software to do that?
-
-
4
Users report mixed real-world performance with DeepSeek models
Multiple commenters on Hacker News report disappointing performance of DeepSeek models in practice despite strong benchmark results. One user finds GLM models more reliable for coding tasks, while another reports DeepSeek gets stuck in loops or produces nonsense outputs.
“I just haven't found them to be very good? I've had a ton more success with the GLM models (since 5.2 anyway). Maybe I'm just holding it wrong, DS models seem to get stuck in loops or tell me nonsense.”
— habosa -
DeepSeek models have such good benchmark performance, amazing pricing, and the team over there seems to be widely considered impressive.I just haven't found them to be very good? I've had a ton more success with the GLM models (since 5.2 anyway). Maybe I'm just holding it wrong, DS models seem to get stuck in loops or tell me nonsense. GLM feels…
-
-
3
Commenter questions lack of comparative analysis in report
A Hacker News commenter criticizes the Enclave report for making a 'best hacking model' claim without providing head-to-head comparisons to competing models like Claude, Gemini, or open-weight alternatives.
“Seems pretty bold to claim deepseek is the "best hacking model" while providing zero comparisons to other models...”
— jrflo -
DeepSeek is underrated. Basically all Chinese models are good enough for day to day coding at this point.The 2 trillion dollar ROI on anthropic alone?Good luck with that.
1 more of the top 2 · 2 posts in this stretch
-
Seems pretty bold to claim deepseek is the "best hacking model" while providing zero comparisons to other models...
-
-
2
Researchers contest the benchmark claim with contrary test results
Hacker News commenter TuxSH reports benchmarking DeepSeek v4.1 Flash against GLM 5.3 on a Nintendo 3DS kernel decomposition task. GLM 5.3 found almost all vulnerabilities in 30 minutes for $22, while DeepSeek found only one vulnerability in 40 minutes for $2, suggesting the model may perform better on low-hanging fruit targets.
“GLM 5.3 founds almost all the vulns in 30min for $22, while DS only found one vuln for $2 in 40min. Perhaps DS works better where targets have low-hanging fruits than can be found fast?”
— TuxSH -
I find this - or perhaps the title - a bit surprising.I've benchmarked GLM 5.3 and DSv4.1-F on my fully-annotated decomp of the Nintendo 3DS's kernel, which I have a good mental understanding of, tasking them to find vulns and other bugs (in Max mode w/ subagents). GLM 5.3 founds almost all the vulns in 30min for $22, while DS only found one vuln…
-
-
1
Audit discovers model used five unexpected attack routes
Enclave's detailed review found the model did not only follow the planned exploit paths. The audit confirmed six solutions matching the designed attack methodology but discovered five additional successful exploitation routes that the original scoring system did not distinguish. For example, in Grafana challenges, DeepSeek placed executable files in a temporary plugin folder rather than using the designed file-path handling vulnerability.
“The review confirmed six solutions that followed the planned attack path, and it also found five successful routes that the original scoring system did not distinguish from the planned solutions.”
— Enclave.ai -
background
Enclave.ai publishes DeepSeek v4.1 Flash benchmark results — Security research firm Enclave.ai releases detailed audit of DeepSeek v4.1 Flash's performance on their AI hacking benchmark. The model achieved perfect scores: code execution on all 11 vulnerable targets (Grafana, Jenkins, Nextcloud instances) while all four fixed/patched versions remained secure. The benchmark run cost only $4.65 due to heavy token caching.
What people are saying 1 voices from 1 site · best of 8 · verbatim
- How does DeepSeek v4.1 Flash compare directly to GPT-4, Claude, and GLM 5.3 on the same hacking benchmark?
- Why do users report practical performance failures when benchmark results are so strong—is it a task-type mismatch or model instability?
- Sep 16
-
we recently got this running in 192gb of vRAM and using it with the Klaudia harness has been incredible for driving out work that we'd need to use Opus and Fable for previously