GoBench benchmark measures LLM reasoning on 9x9 Go against KataGo
A new evaluation framework tests large language models' general reasoning by pitting them against increasingly difficult Go opponents.
What to know
- GoBench evaluates LLMs on 9x9 Go against KataGo opponents, measuring performance from random to superhuman skill levels.
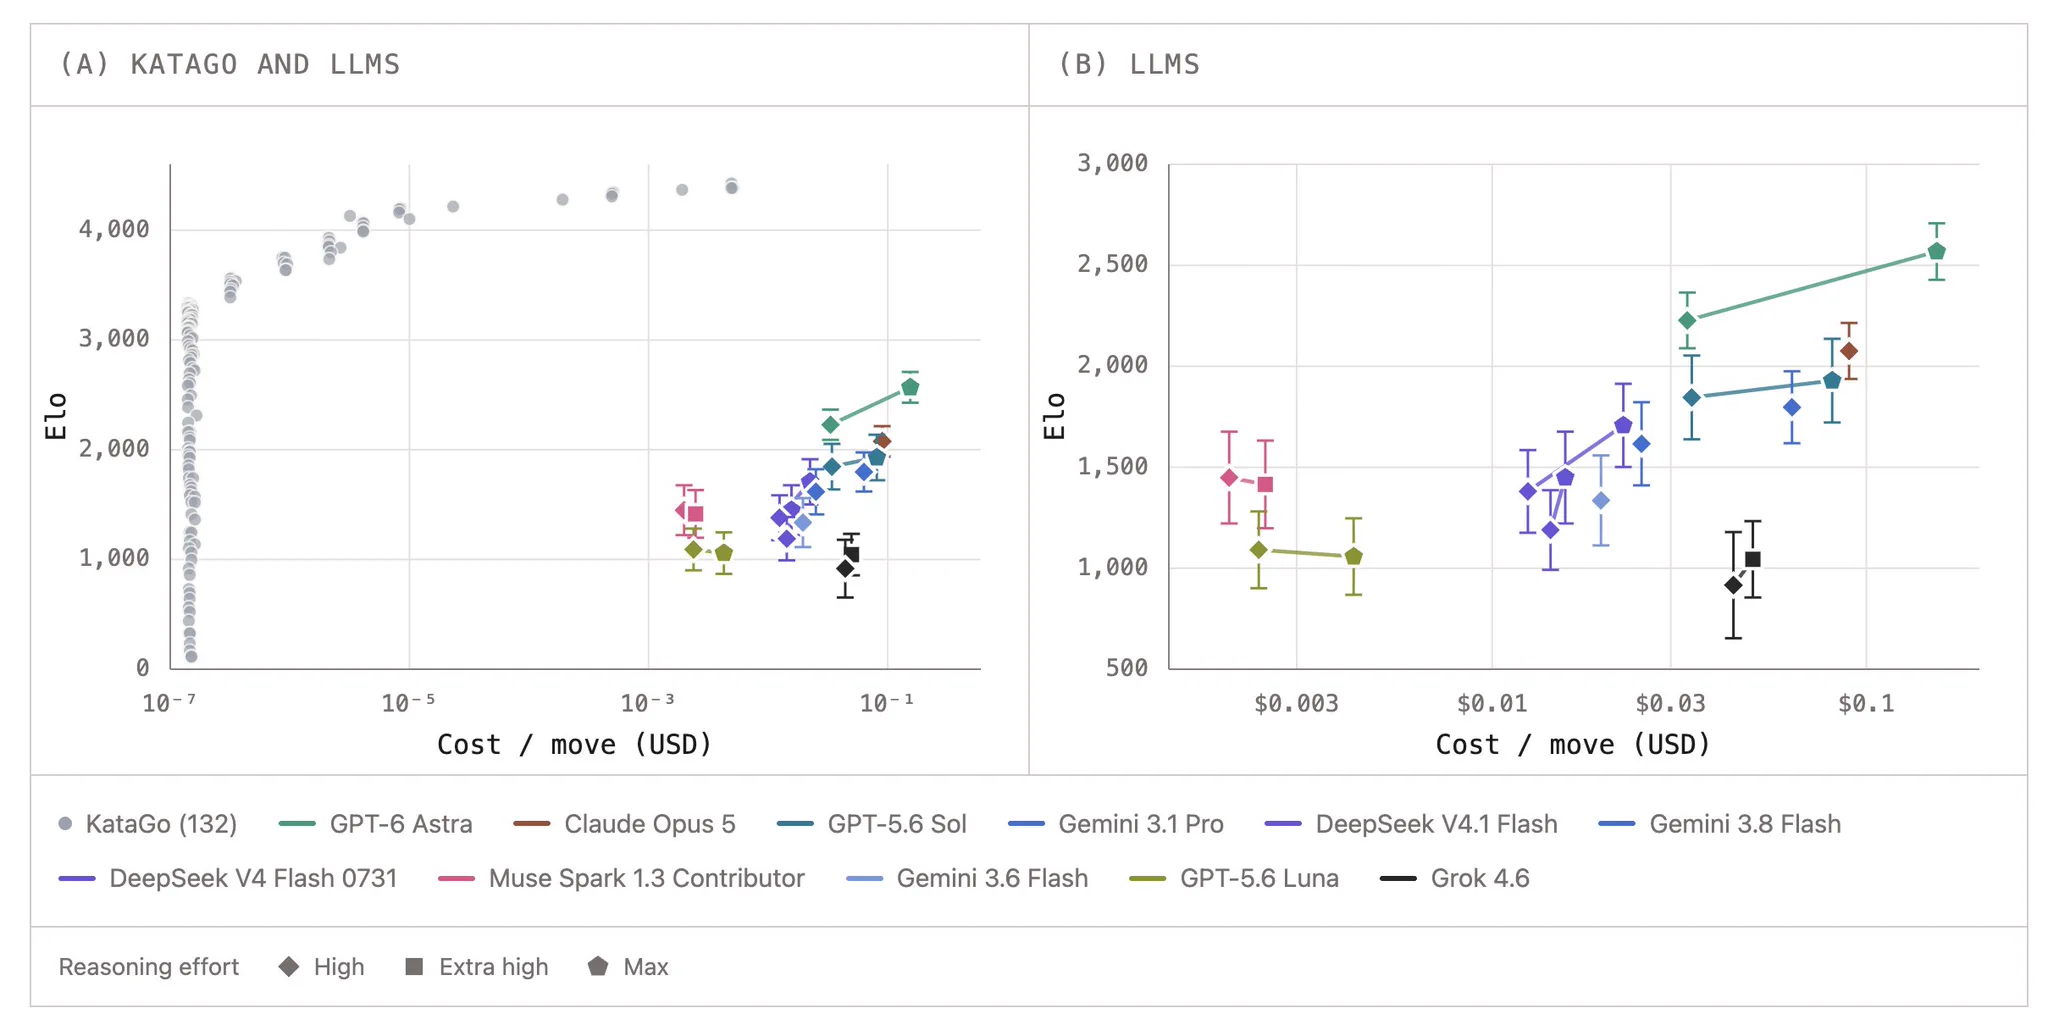
- GPT-6 Astra max reaches 2500 Elo while KataGo achieves 4400 Elo, suggesting significant performance gap.
- The benchmark correlates strongly with ARC-AGI 2 (r=0.83) and remains unsaturated, suggesting room for improvement.
- Debate centers on whether Go performance reflects general reasoning or arbitrary developer design choices.
The dispute Whether GoBench measures genuine out-of-distribution reasoning ability or reflects intentional training by frontier labs on Go capability. · positions read across 3 posts and comments
GoBench is a valid general reasoning measure only if frontier labs did not specifically train on Go.
-
“My reasoning was that Go and ARC-AGI are similar in that they are both out of distribution. I assumed that the frontier labs did not do RL on either of those benchmarks.”
Roland31415 · Reddit ↗
LLM Go performance is an arbitrary developer choice and does not measure genuine reasoning like ARC-AGI intended to.
-
“In contrast, LLMs doing very well at chess or go is a totally arbitrary decision by the developers. The training data costs $0. It measures general reasoning ability I don't think so.”
we_are_mammals · Reddit ↗
Roland31415 GoBench creator
How it unfolded 4 developments, newest first · click a bar or a number to jump postscomments
-
4
Roland31415 responds that Go is out-of-distribution if labs did not specifically train on it
The creator responds that Go and ARC-AGI are similar as out-of-distribution tasks, and argues GoBench can only measure general reasoning if frontier labs did not specifically train on Go. He notes Go data might exist slightly in pretraining but shouldn't affect results much.
“It is true that GoBench can only measure general reasoning if the frontier labs do not specifically train on Go.”
— Roland31415 -
My reasoning was that Go and ARC-AGI are similar in that they are both out of distribution. I assumed that the frontier labs did not do RL on either of those benchmarks. Go data might exist slightly in pretraining, but that shouldnt affect the results much. It is true that GoBench can only measure general reasoning if the frontier labs do not…
-
-
3
Commenter questions whether GoBench measures general reasoning or arbitrary capability
A commenter challenges the claim that GoBench measures general reasoning, arguing that LLM performance on Go is an arbitrary developer choice unlike ARC-AGI's attempt at true unsolved problems, and that Go training data costs nearly nothing.
“In contrast, LLMs doing very well at chess or go is a totally arbitrary decision by the developers. The training data costs $0. It measures general reasoning ability I don't think so.”
— we_are_mammals -
strongly correlates with ARC-AGI 2 (r=0.83 correlation), and remains highly unsaturated. This is missing the point of ARC-AGI. They thought that their data would be impossible to generate automatically. Chollet actually claimed something like that in a video interview. They were wrong, but at least they tried. In contrast, LLMs doing very well at…
-
-
2
GoBench details reveal benchmark correlation with ARC-AGI 2 and remaining unsaturation
Further details show GoBench strongly correlates with ARC-AGI 2 at r=0.83, measures general reasoning ability, and remains unsaturated. With coding tools and two hours of preparation, Codex with Astra achieves 3560 Elo. The creator plans to maintain the leaderboard as long as it remains unsaturated.
“It measures general reasoning ability, strongly correlates with ARC-AGI 2 (r=0.83 correlation), and remains highly unsaturated.”
— Roland31415 -
1
Roland31415 introduces GoBench LLM evaluation framework
GoBench evaluates large language models by having them play 9x9 Go against a ladder of KataGo opponents from random to superhuman skill. GPT-6 Astra max, the strongest LLM tested, achieves 2500 Elo compared to KataGo's 4400 Elo peak.
“Introducing GoBench, where LLMs play 9x9 Go against KataGo players, from random to superhuman.”
— @Roland65821498 -
Introducing GoBench, where LLMs play 9x9 Go against KataGo players, from random to superhuman. The strongest LLM is GPT-6 Astra max at 2500 Elo. GoBench is far from saturation: KataGo can achieve 3300 Elo while costing a million times less, or 4400 Elo while costing 10x less.
-